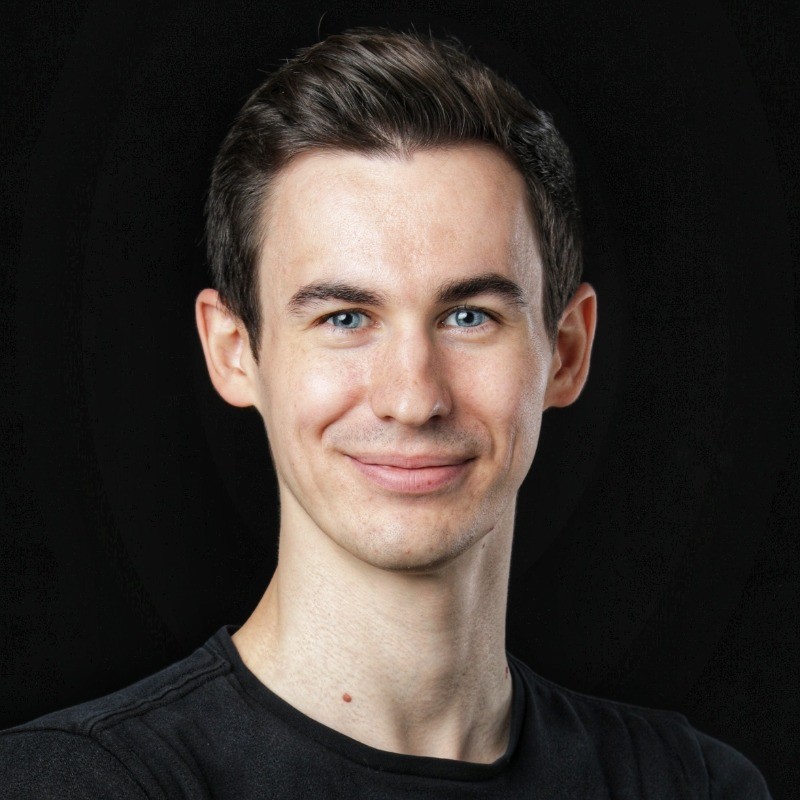
Stefan Schöpf, PhD
Quant & AI Researcher
I'm a Quant and AI Researcher at a multi-billion USD global macro hedge fund, working with messy, large-scale alternative data. My work spans the full cycle from research to deployment: researching multi-agent AI systems, designing rigorous backtesting environments, and deploying solutions into production. My PhD at Cambridge and a research stint at Google DeepMind focused on machine unlearning; at IBM Research, I built multi-agent AI systems to red-team LLMs. Both inform how I build robust agentic systems today. Before my PhD, I was a strategy consultant at BCG and co-founded an ML startup analysing satellite imagery for earth observation.
Career Timeline
 Quant, ML & Agentic AIJJJ CapitalMar 2026 – Present
 PhD Researcher (Intern)Google DeepMindDec 2024 – Sep 2025
 PhD Researcher (Intern)IBM ResearchJun – Sep 2024
 PhD CandidateUniversity of CambridgeOct 2022 – Mar 2026
 AssociateBCG2021 – 2022
 MScETH Zürich2019 – 2021
 Co-FounderAudili2018 – 2021
 BScTU Graz2015 – 2018
Selected Publications
Click a paper for its abstract
Machine learning models have an increasingly established presence in almost all aspects of our daily lives, ranging from news feed recommendations to predicting the delivery date of global shipments. This is driven by recent technological advancements and unprecedented amounts of training data. However, as the field of machine learning advances rapidly, we have to ensure that models only contain information from training data that are (a) not corrupted, i.e. reflect the true state of the world; and (b) permissible, i.e. not violating regulations such as copyright and privacy via inclusion of sensitive data. In practice, data preparation and unwanted data mitigation processes are imperfect, inevitably resulting in the inclusion of information learned from such unwanted data in the trained model. Retraining a new model from scratch without the unwanted data is possible, but as models grow in size and complexity, they are increasingly costly and time-intensive to train and deploy, making this option economically undesirable. This thesis advances foundational and applied research towards enabling machine learning models to contain only information from data that is permissible and free of corruptions, approached from two directions: removing unwanted data from already trained models, and mitigation at learning time. Contributions include a method that avoids compute-intensive fine-tuning epochs or hyperparameter tuning, the discovery and remedy of previously unknown method failures in corrupted-data unlearning, the first case study of machine unlearning in supply chains, and a method for multi-owner settings that keeps both model parameters and data local.
Machine unlearning is studied for a multitude of tasks, but specialization of unlearning methods to particular tasks has made their systematic comparison challenging. To address this issue, we propose a conceptual space to characterize diverse corrupted data unlearning tasks in vision classifiers. This space is described by two dimensions: the discovery rate (the fraction of the corrupted data known at unlearning time) and the statistical regularity of the corrupted data (from random exemplars to shared concepts). Methods proposed previously have been targeted at portions of this space and — we show — fail predictably outside these regions. We propose a novel method, Redirection for Erasing Memory (REM), whose key feature is that corrupted data are redirected to dedicated neurons introduced at unlearning time and then discarded or deactivated to suppress their influence. REM performs strongly across the space of tasks, in contrast to prior state-of-the-art methods that fail outside the regions for which they were designed.
With LLM usage rapidly increasing, their vulnerability to jailbreaks that create harmful outputs are a major security risk. As new jailbreaking strategies emerge and models are changed by fine-tuning, continuous testing for security vulnerabilities is necessary. Existing red-teaming methods fall short in cost efficiency, attack success rate, attack diversity, or extensibility as new attack types emerge. We address these challenges with Modular And Diverse Malicious Attack MiXtures (MAD-MAX) for Automated LLM Red Teaming. MAD-MAX automatically assigns attack strategies into relevant attack clusters, chooses the most relevant clusters for a malicious goal, and combines strategies from the selected clusters to achieve diverse novel attacks with high attack success rates. It further merges promising attacks together at each iteration and introduces a similarity filter to prune out similar attacks for increased cost efficiency. MAD-MAX outperforms the prominent red-teaming method Tree of Attacks with Pruning (TAP) significantly: it jailbreaks 97% of malicious goals on GPT-4o and Gemini-Pro, compared to TAP's 66%, using only 10.9 average queries to the target LLM versus TAP's 23.3.
As generative AI, particularly large language models (LLMs), becomes increasingly integrated into production applications, new attack surfaces and vulnerabilities emerge and put a focus on adversarial threats in natural language and multi-modal systems. Red-teaming has gained importance in proactively identifying weaknesses in these systems, while blue-teaming works to protect against such adversarial attacks. Despite growing academic interest in adversarial risks for generative AI, there is limited guidance tailored for practitioners to assess and mitigate these challenges in real-world environments. Our contributions include a practical examination of red- and blue-teaming strategies for securing generative AI, identification of key challenges and open questions in defense development and evaluation, and the Attack Atlas — an intuitive framework that brings a practical approach to analyzing single-turn input attacks, placing it at the forefront for practitioners. This work aims to bridge the gap between academic insights and practical security measures for the protection of generative AI systems.
Adversarial attacks by malicious actors on machine learning systems, such as introducing poison triggers into training datasets, pose significant risks. The challenge in resolving such an attack arises in practice when only a subset of the poisoned data can be identified, requiring methods to unlearn poison triggers from already trained models with only a subset of the poison data available — a setting that deviates significantly from privacy-focused unlearning, where all data to be forgotten is known. Prior work has shown that undiscovered poisoned samples cause established unlearning methods to fail, with only Selective Synaptic Dampening (SSD) showing limited success; even full retraining after removing identified poison cannot address this, as undiscovered samples reintroduce the trigger. We address two challenges to advance the state of the art: a novel outlier-resistant method, based on SSD, that significantly improves model protection and unlearning performance; and Poison Trigger Neutralisation (PTN) search, a fast, parallelisable hyperparameter search that exploits the "unlearning versus model protection" trade-off for settings where the forget set size is unknown and the retain set is contaminated. Benchmarked on ResNet-9/CIFAR10 and WideResNet-28x10/CIFAR100, our method heals 93.72% of poison compared to SSD's 83.41% and full retraining's 40.68%, while lowering the average accuracy drop from unlearning from 5.68% (SSD) to 1.41% (ours).
Machine unlearning, the ability for a machine learning model to forget, is becoming increasingly important to comply with data privacy regulations, as well as to remove harmful, manipulated, or outdated information. The key challenge lies in forgetting specific information while protecting model performance on the remaining data. While current state-of-the-art methods perform well, they typically require some level of retraining over the retained data, which adds computational overhead and mandates that the training data remain available and accessible. In contrast, retrain-free methods are prohibitively computationally expensive and do not perform on par with their retrain-based counterparts. We present Selective Synaptic Dampening (SSD), a novel two-step, post hoc, retrain-free approach to machine unlearning that is fast, performant, and does not require long-term storage of the training data. First, SSD uses the Fisher information matrix of the training and forgetting data to select parameters disproportionately important to the forget set. Second, SSD induces forgetting by dampening these parameters proportional to their relative importance to the forget set with respect to the wider training data. Results show that the performance of SSD is competitive with retrain-based post hoc methods, demonstrating the viability of retrain-free post hoc unlearning approaches.